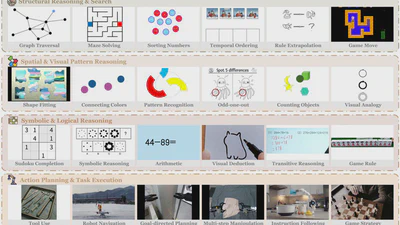
ThinkVid: Benchmarking Visual Reasoning in Video Generative Models
Benchmarking visual reasoning in video generation.
Harold Haodong Chen
Benchmarking visual reasoning in video generation.
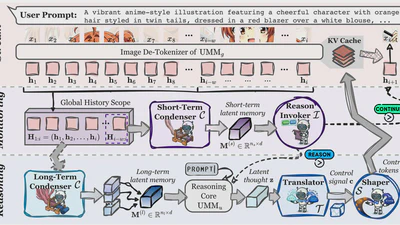
A framework that integrates implicit latent reasoning into autoregressive text-to-image generation.
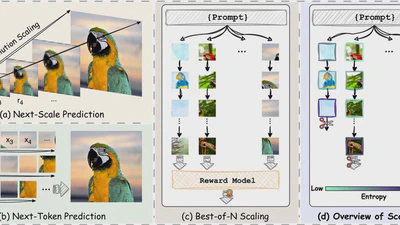
Confidence scaling for better autoregressive image generation.
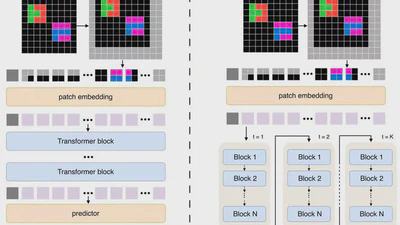
Looped (weight-tied) Transformers for Visual ARC—scale reasoning with “thinking time”.

Training-free attention scaling for text-guided image-to-video semantic fidelity.
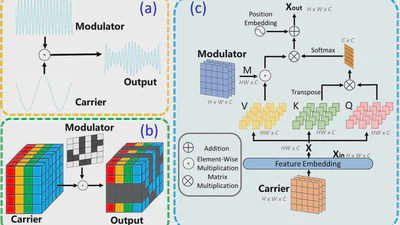
Cross Modulation Transformer with frequency-domain hybrid loss for pansharpening.
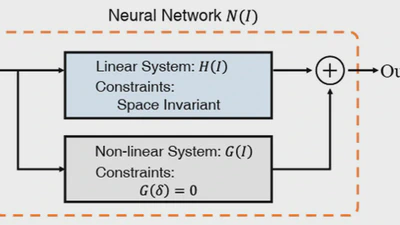
We explore frequency behavior in super-resolution models and its impact on reconstruction performance.